CLI, MCP, or the browser
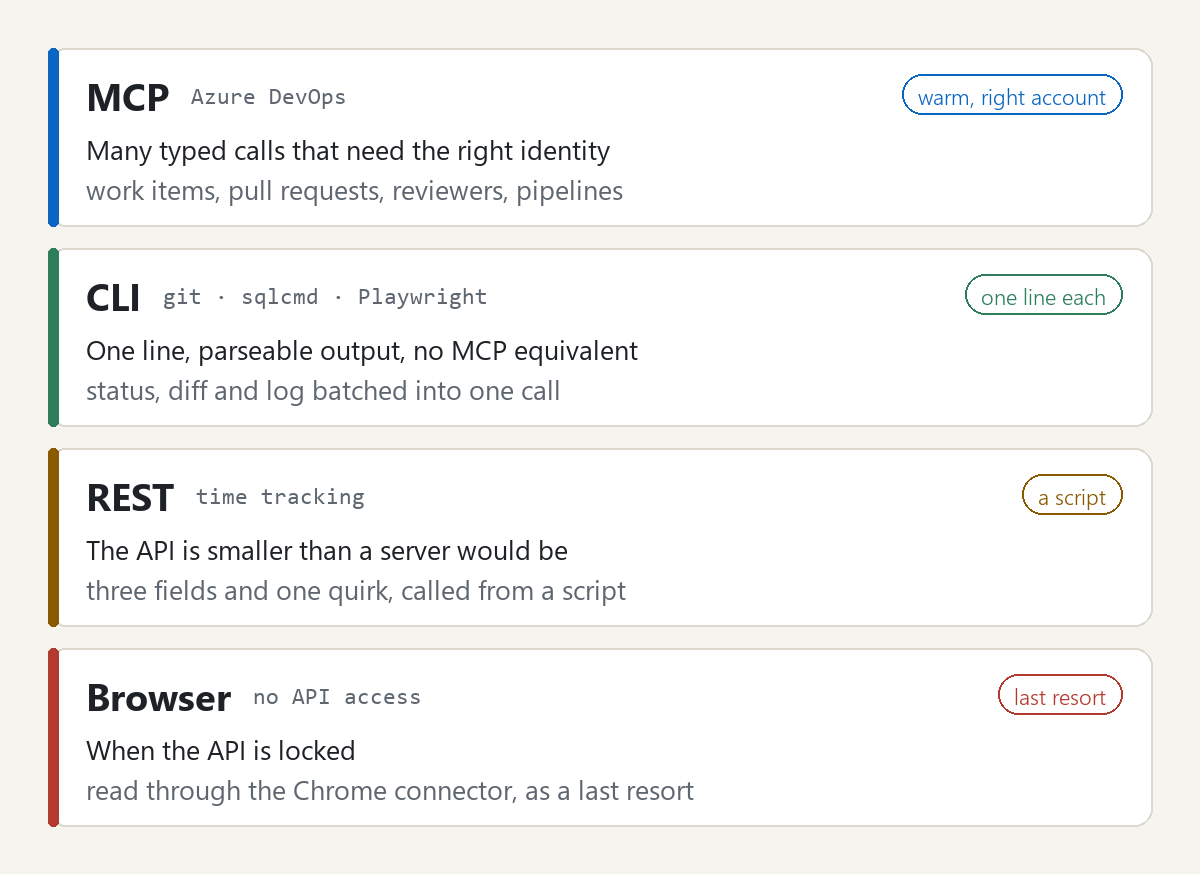
Every system Claude Code touches gets one route. CLI, MCP, raw REST or the browser. I keep the table written down, and I started it the day a pull request went out under the wrong name.
The rule is short. MCP when the calls are many, typed, and need the right identity. CLI when it's one line with no MCP equivalent. Raw REST when the API is smaller than a server would be. The browser when the API is locked.
The pull request taught me the identity half. Where I work, Azure DevOps and our Azure resources sit in two different tenants. The az CLI logs into resources by default, and the DevOps identity lives in a second config directory. An az repos call that doesn't name the right one still succeeds. It just opens the PR as the other account, and a PR's author can't be changed afterward. The only fix is to abandon it and start again.
Azure DevOps goes through an MCP server. Work items, comments, parent links, PR create, reviewers, auto-complete, pipelines. Two reasons. The server authenticates as the right account on every call. And it's already warm. Each az invocation pays two to four seconds of cold start, and the ship pipeline makes a dozen calls in a row. On the happy path it makes zero az calls. The one exception is linking a work item to an existing PR, which has no MCP equivalent. A hook from part 4 covers it. It doesn't block az. It blocks a DevOps call that doesn't name the account, and its refusal names both fixes, the pinned form and the MCP tools, so Claude corrects itself in one turn.
Time logging goes through raw REST from a script. The API is three fields and one quirk. Every POST returns a 500 and succeeds anyway. An MCP server for that would be more surface than the API has.
git, sqlcmd, Playwright and the function-app publish stay on the CLI. One line each, parseable output, nothing to choose between. The speed rule there is batching, so status, diff and log go in one call, not three.
MCP also charges rent. Every tool definition sits in context on every turn whether you call it or not, which is why this project enables one server, not one per system.
Two things I got wrong first. My own reference doc named MCP tools from an older server version that no longer existed, and Claude called them until I fixed the doc. And I let tool-schema fetches happen mid-pipeline. Now the first turn loads every MCP tool the run needs in one call, so nothing stalls later.
Pick the route per system, not per preference. Then write the table where the model will read it, because left alone it reaches for az every time.
Setting Up Claude, part 5 of 10. Next: Plan first, then build.